
2/7
Rig Ved 1.43.8
Here it says that there are two types of people who can cause harm to your yagya. One are the misers who although have everything, but they will not help you. The others can cause you harm by taking away the things accumulated for yagya.
1/7

2/7
मा नः॑ सोमपरि॒बाधो॒ मारा॑तयो जुहुरंत ।
आ न॑ इंदो॒ वाजे॑ भज ॥
3/7
सोमपरिबाधः - Creating problems in Som yagya.
नः - We.
मा - No.
जुहुरन्त - Violent.
अरातयः - Enemy.
इन्दो - Oh Som!
वाजे - Strength/good grains.
आ भजः - Give from all aspects.
Explanation; We request you to protect us from the enemies who
4/7
Deep meaning:-Here it says that there are two types of people who can cause harm to your yagya. One are the misers who although
5/7
6/7
7/7
https://t.co/joBAU3KCL0
Facebook page link👇
https://t.co/Y6ziyIZnS4
Instagram link👇
https://t.co/WF8bFXrqTw
#RigVedPositivity
#InspiredByAnjaninandanDass
📸 Credit - Rajesh N Sir
https://t.co/W2jnWlziJC
More from Anshul Pandey




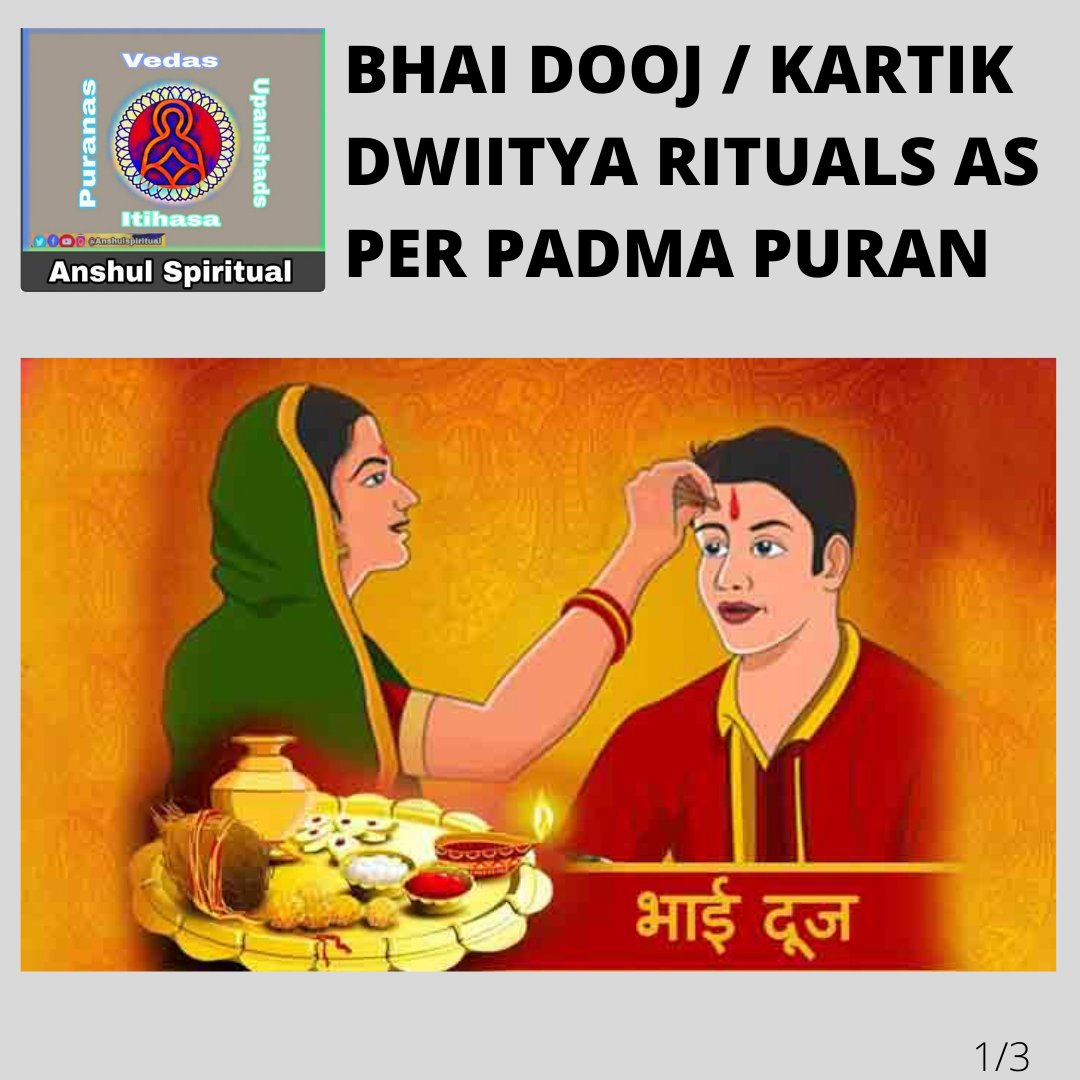
BHAI DOOJ / KARTIK DWIITYA RITUALS AS PER PADMA PURAN!
https://t.co/Nk49jADuXS
https://t.co/CqYE2aVHCI
Instagram link👇
https://t.co/UmeHgDSP0a
Facebook page link👇
https://t.co/LFtkDQeBvI
Happy Bhai Dooj to all!
#InspiredBySwamiAnjaninandanDass
Just in case if you have not subscribed to my youtube channel, please do subscribe, I have already posted 9 Videos till now on different subjects, Specially Mythbusters topics. Do watch them and give your feedback in comments
https://t.co/Nk49jADuXS
https://t.co/CqYE2aVHCI
Instagram link👇
https://t.co/UmeHgDSP0a
Facebook page link👇
https://t.co/LFtkDQeBvI
Happy Bhai Dooj to all!
#InspiredBySwamiAnjaninandanDass
Just in case if you have not subscribed to my youtube channel, please do subscribe, I have already posted 9 Videos till now on different subjects, Specially Mythbusters topics. Do watch them and give your feedback in comments
More from All




How can we use language supervision to learn better visual representations for robotics?
Introducing Voltron: Language-Driven Representation Learning for Robotics!
Paper: https://t.co/gIsRPtSjKz
Models: https://t.co/NOB3cpATYG
Evaluation: https://t.co/aOzQu95J8z
🧵👇(1 / 12)
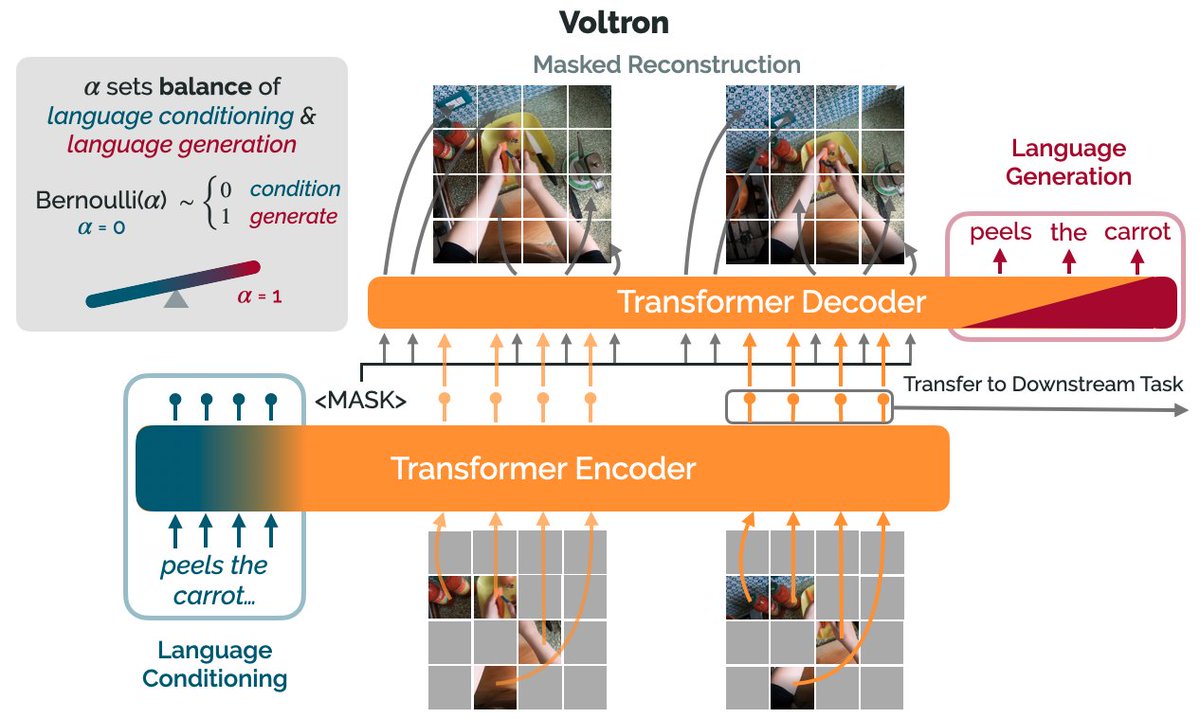
Videos of humans performing everyday tasks (Something-Something-v2, Ego4D) offer a rich and diverse resource for learning representations for robotic manipulation.
Yet, an underused part of these datasets are the rich, natural language annotations accompanying each video. (2/12)
The Voltron framework offers a simple way to use language supervision to shape representation learning, building off of prior work in representations for robotics like MVP (https://t.co/Pb0mk9hb4i) and R3M (https://t.co/o2Fkc3fP0e).
The secret is *balance* (3/12)
Starting with a masked autoencoder over frames from these video clips, make a choice:
1) Condition on language and improve our ability to reconstruct the scene.
2) Generate language given the visual representation and improve our ability to describe what's happening. (4/12)
By trading off *conditioning* and *generation* we show that we can learn 1) better representations than prior methods, and 2) explicitly shape the balance of low and high-level features captured.
Why is the ability to shape this balance important? (5/12)
Introducing Voltron: Language-Driven Representation Learning for Robotics!
Paper: https://t.co/gIsRPtSjKz
Models: https://t.co/NOB3cpATYG
Evaluation: https://t.co/aOzQu95J8z
🧵👇(1 / 12)
Videos of humans performing everyday tasks (Something-Something-v2, Ego4D) offer a rich and diverse resource for learning representations for robotic manipulation.
Yet, an underused part of these datasets are the rich, natural language annotations accompanying each video. (2/12)
The Voltron framework offers a simple way to use language supervision to shape representation learning, building off of prior work in representations for robotics like MVP (https://t.co/Pb0mk9hb4i) and R3M (https://t.co/o2Fkc3fP0e).
The secret is *balance* (3/12)
Starting with a masked autoencoder over frames from these video clips, make a choice:
1) Condition on language and improve our ability to reconstruct the scene.
2) Generate language given the visual representation and improve our ability to describe what's happening. (4/12)
By trading off *conditioning* and *generation* we show that we can learn 1) better representations than prior methods, and 2) explicitly shape the balance of low and high-level features captured.
Why is the ability to shape this balance important? (5/12)

You May Also Like

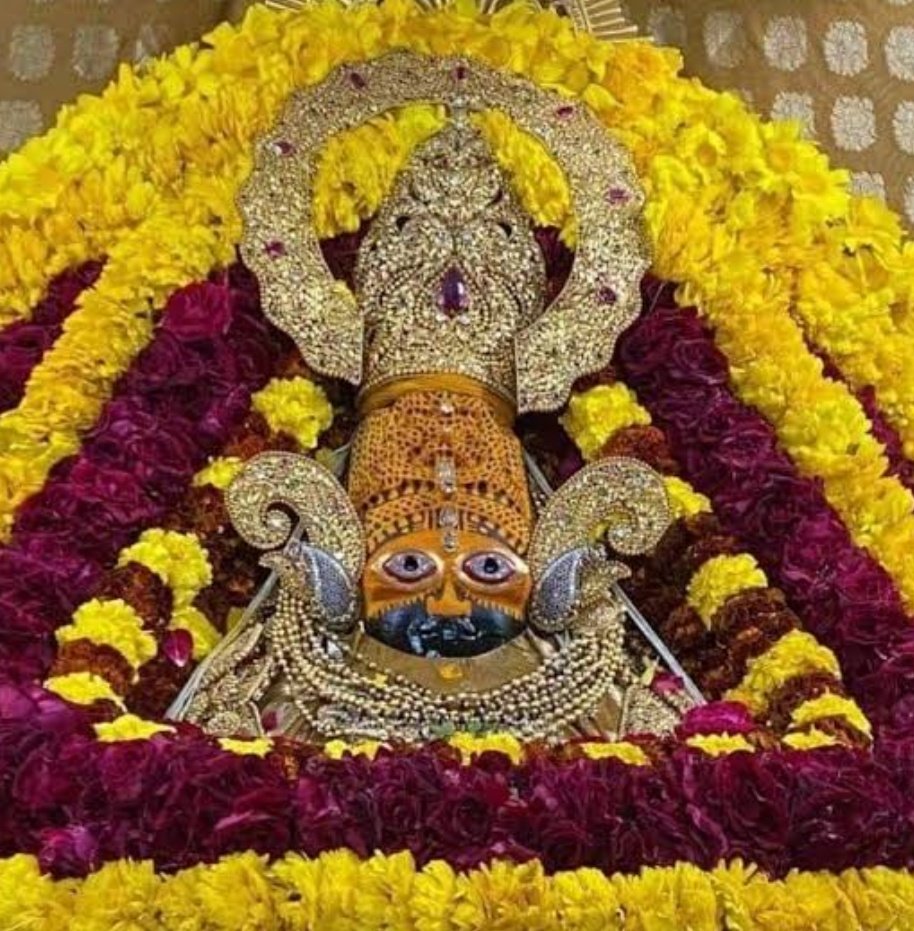
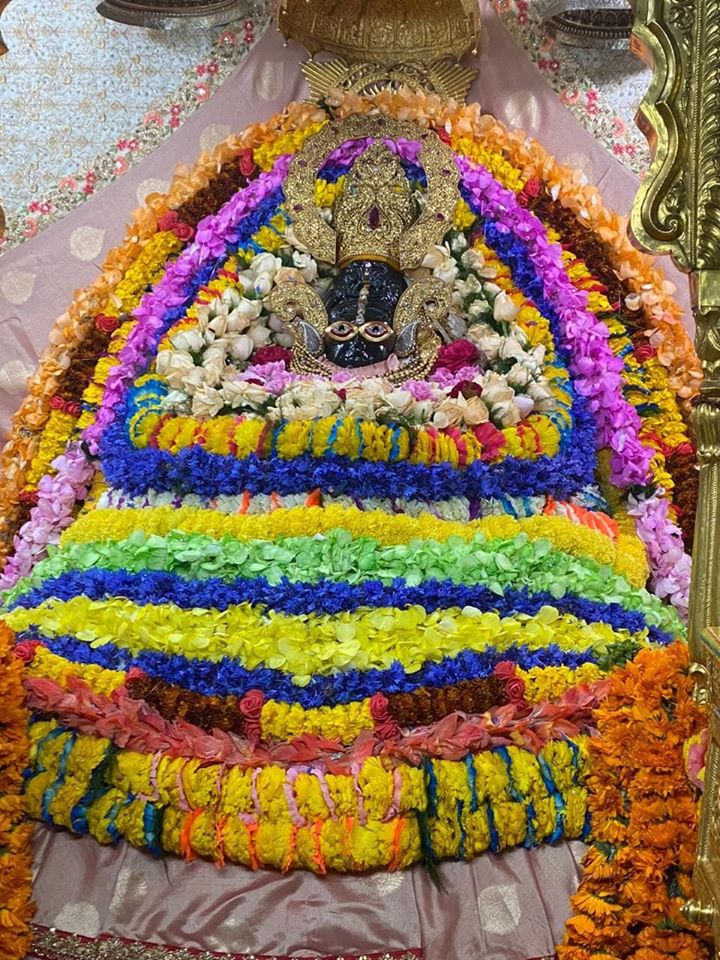

Margatha Natarajar murthi - Uthirakosamangai temple near Ramanathapuram,TN
#ArudraDarisanam
Unique Natarajar made of emerlad is abt 6 feet tall.
It is always covered with sandal paste.Only on Thriuvadhirai Star in month Margazhi-Nataraja can be worshipped without sandal paste.
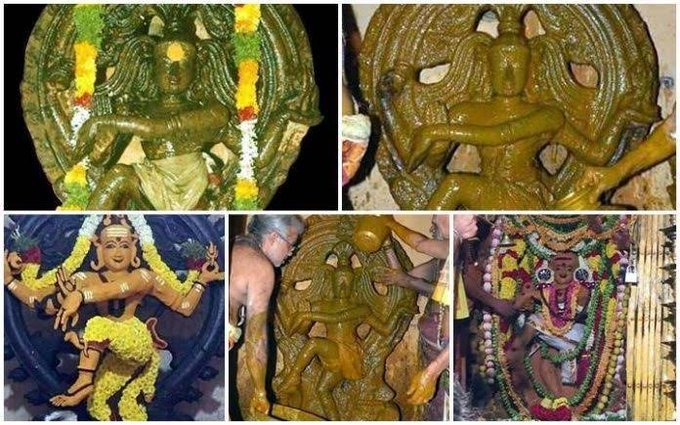
After removing the sandal paste,day long rituals & various abhishekam will be https://t.co/e1Ye8DrNWb day Maragatha Nataraja sannandhi will be closed after anointing the murthi with fresh sandal paste.Maragatha Natarajar is covered with sandal paste throughout the year
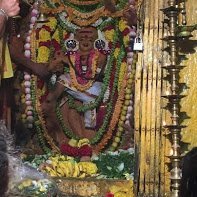
as Emerald has scientific property of its molecules getting disturbed when exposed to light/water/sound.This is an ancient Shiva temple considered to be 3000 years old -believed to be where Bhagwan Shiva gave Veda gyaana to Parvati Devi.This temple has some stunning sculptures.
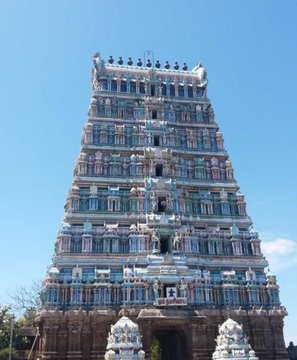
#ArudraDarisanam
Unique Natarajar made of emerlad is abt 6 feet tall.
It is always covered with sandal paste.Only on Thriuvadhirai Star in month Margazhi-Nataraja can be worshipped without sandal paste.
After removing the sandal paste,day long rituals & various abhishekam will be https://t.co/e1Ye8DrNWb day Maragatha Nataraja sannandhi will be closed after anointing the murthi with fresh sandal paste.Maragatha Natarajar is covered with sandal paste throughout the year
as Emerald has scientific property of its molecules getting disturbed when exposed to light/water/sound.This is an ancient Shiva temple considered to be 3000 years old -believed to be where Bhagwan Shiva gave Veda gyaana to Parvati Devi.This temple has some stunning sculptures.


