Yes, I am talking about the Food Preparation time that @zomato displays on their app after the user orders food.
I ordered a pizza from @zomato recently. I thought this feature was a simple implementation, but this shocked me when I got to know the reality.
A Thread 🧵
Yes, I am talking about the Food Preparation time that @zomato displays on their app after the user orders food.
I was amazed after knowing this, and here is how they implement this to achieve accurate results.
But more factors are in play here like queued orders, fine dining restaurants vs delivery kitchens, opening hours, etc.
These categories are encoded using Word2Vec Embedding and Categorical Embedding, respectively.
Concurrently they passed both running orders and completed orders through a stacked LSTM layer.
The resulting vector after concatenation is pass through a two-layer dense network to get food preparation time.
More from All

Took me 5 years to get the best Chartink scanners for Stock Market, but you’ll get it in 5 mminutes here ⏰
Do Share the above tweet 👆
These are going to be very simple yet effective pure price action based scanners, no fancy indicators nothing - hope you liked it.
https://t.co/JU0MJIbpRV
52 Week High
One of the classic scanners very you will get strong stocks to Bet on.
https://t.co/V69th0jwBr
Hourly Breakout
This scanner will give you short term bet breakouts like hourly or 2Hr breakout
Volume shocker
Volume spurt in a stock with massive X times
Do Share the above tweet 👆
These are going to be very simple yet effective pure price action based scanners, no fancy indicators nothing - hope you liked it.
https://t.co/JU0MJIbpRV
52 Week High
One of the classic scanners very you will get strong stocks to Bet on.
https://t.co/V69th0jwBr
Hourly Breakout
This scanner will give you short term bet breakouts like hourly or 2Hr breakout
Volume shocker
Volume spurt in a stock with massive X times





How can we use language supervision to learn better visual representations for robotics?
Introducing Voltron: Language-Driven Representation Learning for Robotics!
Paper: https://t.co/gIsRPtSjKz
Models: https://t.co/NOB3cpATYG
Evaluation: https://t.co/aOzQu95J8z
🧵👇(1 / 12)
Videos of humans performing everyday tasks (Something-Something-v2, Ego4D) offer a rich and diverse resource for learning representations for robotic manipulation.
Yet, an underused part of these datasets are the rich, natural language annotations accompanying each video. (2/12)
The Voltron framework offers a simple way to use language supervision to shape representation learning, building off of prior work in representations for robotics like MVP (https://t.co/Pb0mk9hb4i) and R3M (https://t.co/o2Fkc3fP0e).
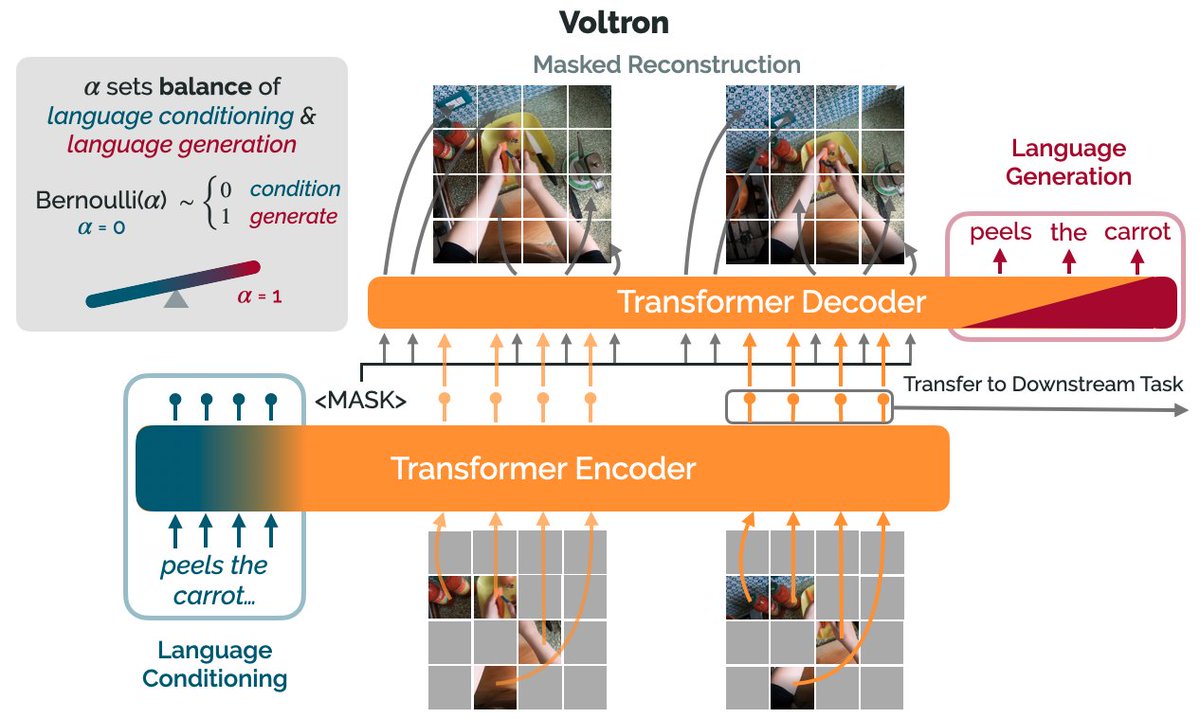
The secret is *balance* (3/12)
Starting with a masked autoencoder over frames from these video clips, make a choice:
1) Condition on language and improve our ability to reconstruct the scene.
2) Generate language given the visual representation and improve our ability to describe what's happening. (4/12)
By trading off *conditioning* and *generation* we show that we can learn 1) better representations than prior methods, and 2) explicitly shape the balance of low and high-level features captured.
Why is the ability to shape this balance important? (5/12)
Introducing Voltron: Language-Driven Representation Learning for Robotics!
Paper: https://t.co/gIsRPtSjKz
Models: https://t.co/NOB3cpATYG
Evaluation: https://t.co/aOzQu95J8z
🧵👇(1 / 12)
Videos of humans performing everyday tasks (Something-Something-v2, Ego4D) offer a rich and diverse resource for learning representations for robotic manipulation.
Yet, an underused part of these datasets are the rich, natural language annotations accompanying each video. (2/12)
The Voltron framework offers a simple way to use language supervision to shape representation learning, building off of prior work in representations for robotics like MVP (https://t.co/Pb0mk9hb4i) and R3M (https://t.co/o2Fkc3fP0e).
The secret is *balance* (3/12)
Starting with a masked autoencoder over frames from these video clips, make a choice:
1) Condition on language and improve our ability to reconstruct the scene.
2) Generate language given the visual representation and improve our ability to describe what's happening. (4/12)
By trading off *conditioning* and *generation* we show that we can learn 1) better representations than prior methods, and 2) explicitly shape the balance of low and high-level features captured.
Why is the ability to shape this balance important? (5/12)