
Favorite furniture brand?
More from All

Margatha Natarajar murthi - Uthirakosamangai temple near Ramanathapuram,TN
#ArudraDarisanam
Unique Natarajar made of emerlad is abt 6 feet tall.
It is always covered with sandal paste.Only on Thriuvadhirai Star in month Margazhi-Nataraja can be worshipped without sandal paste.
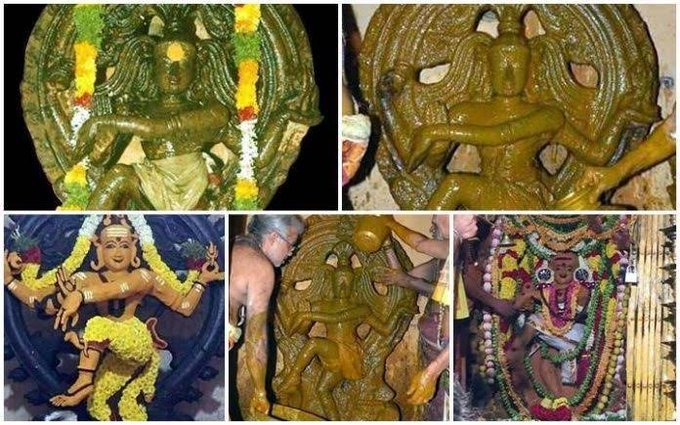
After removing the sandal paste,day long rituals & various abhishekam will be https://t.co/e1Ye8DrNWb day Maragatha Nataraja sannandhi will be closed after anointing the murthi with fresh sandal paste.Maragatha Natarajar is covered with sandal paste throughout the year
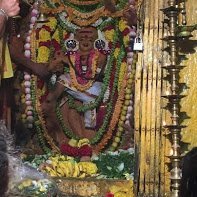
as Emerald has scientific property of its molecules getting disturbed when exposed to light/water/sound.This is an ancient Shiva temple considered to be 3000 years old -believed to be where Bhagwan Shiva gave Veda gyaana to Parvati Devi.This temple has some stunning sculptures.
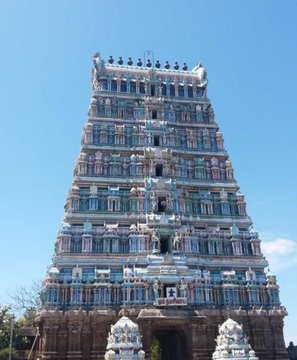
#ArudraDarisanam
Unique Natarajar made of emerlad is abt 6 feet tall.
It is always covered with sandal paste.Only on Thriuvadhirai Star in month Margazhi-Nataraja can be worshipped without sandal paste.
After removing the sandal paste,day long rituals & various abhishekam will be https://t.co/e1Ye8DrNWb day Maragatha Nataraja sannandhi will be closed after anointing the murthi with fresh sandal paste.Maragatha Natarajar is covered with sandal paste throughout the year
as Emerald has scientific property of its molecules getting disturbed when exposed to light/water/sound.This is an ancient Shiva temple considered to be 3000 years old -believed to be where Bhagwan Shiva gave Veda gyaana to Parvati Devi.This temple has some stunning sculptures.


How can we use language supervision to learn better visual representations for robotics?
Introducing Voltron: Language-Driven Representation Learning for Robotics!
Paper: https://t.co/gIsRPtSjKz
Models: https://t.co/NOB3cpATYG
Evaluation: https://t.co/aOzQu95J8z
🧵👇(1 / 12)
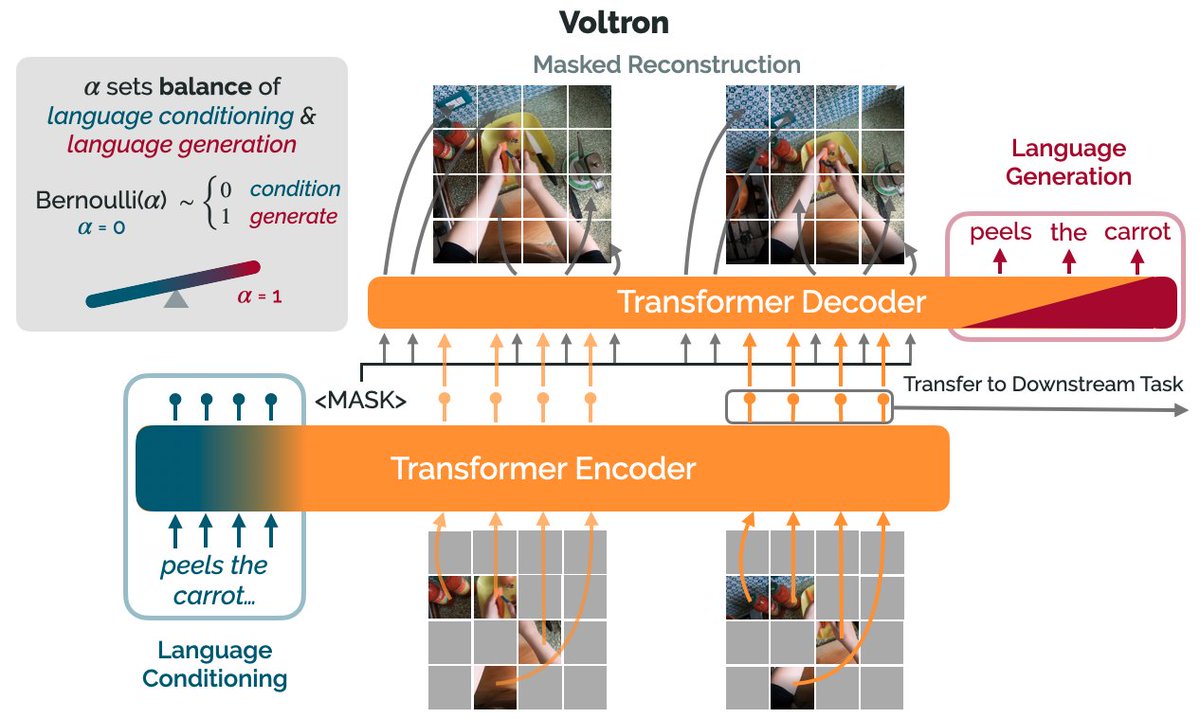
Videos of humans performing everyday tasks (Something-Something-v2, Ego4D) offer a rich and diverse resource for learning representations for robotic manipulation.
Yet, an underused part of these datasets are the rich, natural language annotations accompanying each video. (2/12)
The Voltron framework offers a simple way to use language supervision to shape representation learning, building off of prior work in representations for robotics like MVP (https://t.co/Pb0mk9hb4i) and R3M (https://t.co/o2Fkc3fP0e).
The secret is *balance* (3/12)
Starting with a masked autoencoder over frames from these video clips, make a choice:
1) Condition on language and improve our ability to reconstruct the scene.
2) Generate language given the visual representation and improve our ability to describe what's happening. (4/12)
By trading off *conditioning* and *generation* we show that we can learn 1) better representations than prior methods, and 2) explicitly shape the balance of low and high-level features captured.
Why is the ability to shape this balance important? (5/12)
Introducing Voltron: Language-Driven Representation Learning for Robotics!
Paper: https://t.co/gIsRPtSjKz
Models: https://t.co/NOB3cpATYG
Evaluation: https://t.co/aOzQu95J8z
🧵👇(1 / 12)
Videos of humans performing everyday tasks (Something-Something-v2, Ego4D) offer a rich and diverse resource for learning representations for robotic manipulation.
Yet, an underused part of these datasets are the rich, natural language annotations accompanying each video. (2/12)
The Voltron framework offers a simple way to use language supervision to shape representation learning, building off of prior work in representations for robotics like MVP (https://t.co/Pb0mk9hb4i) and R3M (https://t.co/o2Fkc3fP0e).
The secret is *balance* (3/12)
Starting with a masked autoencoder over frames from these video clips, make a choice:
1) Condition on language and improve our ability to reconstruct the scene.
2) Generate language given the visual representation and improve our ability to describe what's happening. (4/12)
By trading off *conditioning* and *generation* we show that we can learn 1) better representations than prior methods, and 2) explicitly shape the balance of low and high-level features captured.
Why is the ability to shape this balance important? (5/12)


You May Also Like





1/“What would need to be true for you to….X”
Why is this the most powerful question you can ask when attempting to reach an agreement with another human being or organization?
A thread, co-written by @deanmbrody:
2/ First, “X” could be lots of things. Examples: What would need to be true for you to
- “Feel it's in our best interest for me to be CMO"
- “Feel that we’re in a good place as a company”
- “Feel that we’re on the same page”
- “Feel that we both got what we wanted from this deal
3/ Normally, we aren’t that direct. Example from startup/VC land:
Founders leave VC meetings thinking that every VC will invest, but they rarely do.
Worse over, the founders don’t know what they need to do in order to be fundable.
4/ So why should you ask the magic Q?
To get clarity.
You want to know where you stand, and what it takes to get what you want in a way that also gets them what they want.
It also holds them (mentally) accountable once the thing they need becomes true.
5/ Staying in the context of soliciting investors, the question is “what would need to be true for you to want to invest (or partner with us on this journey, etc)?”
Multiple responses to this question are likely to deliver a positive result.
Why is this the most powerful question you can ask when attempting to reach an agreement with another human being or organization?
A thread, co-written by @deanmbrody:
Next level tactic when closing a sale, candidate, or investment:
— Erik Torenberg (@eriktorenberg) February 27, 2018
Ask: \u201cWhat needs to be true for you to be all in?\u201d
You'll usually get an explicit answer that you might not get otherwise. It also holds them accountable once the thing they need becomes true.
2/ First, “X” could be lots of things. Examples: What would need to be true for you to
- “Feel it's in our best interest for me to be CMO"
- “Feel that we’re in a good place as a company”
- “Feel that we’re on the same page”
- “Feel that we both got what we wanted from this deal
3/ Normally, we aren’t that direct. Example from startup/VC land:
Founders leave VC meetings thinking that every VC will invest, but they rarely do.
Worse over, the founders don’t know what they need to do in order to be fundable.
4/ So why should you ask the magic Q?
To get clarity.
You want to know where you stand, and what it takes to get what you want in a way that also gets them what they want.
It also holds them (mentally) accountable once the thing they need becomes true.
5/ Staying in the context of soliciting investors, the question is “what would need to be true for you to want to invest (or partner with us on this journey, etc)?”
Multiple responses to this question are likely to deliver a positive result.
