
In 2 minutes, I'll give you 13 tips for beating procrastination...
@Ant_Philosophy
I created this account to help:
• You become the best version of yourself.
• Provide inspiration and motivation.
• You learn alongside me on my journey.
Have an amazing day :)
More from All




How can we use language supervision to learn better visual representations for robotics?
Introducing Voltron: Language-Driven Representation Learning for Robotics!
Paper: https://t.co/gIsRPtSjKz
Models: https://t.co/NOB3cpATYG
Evaluation: https://t.co/aOzQu95J8z
🧵👇(1 / 12)
Videos of humans performing everyday tasks (Something-Something-v2, Ego4D) offer a rich and diverse resource for learning representations for robotic manipulation.
Yet, an underused part of these datasets are the rich, natural language annotations accompanying each video. (2/12)
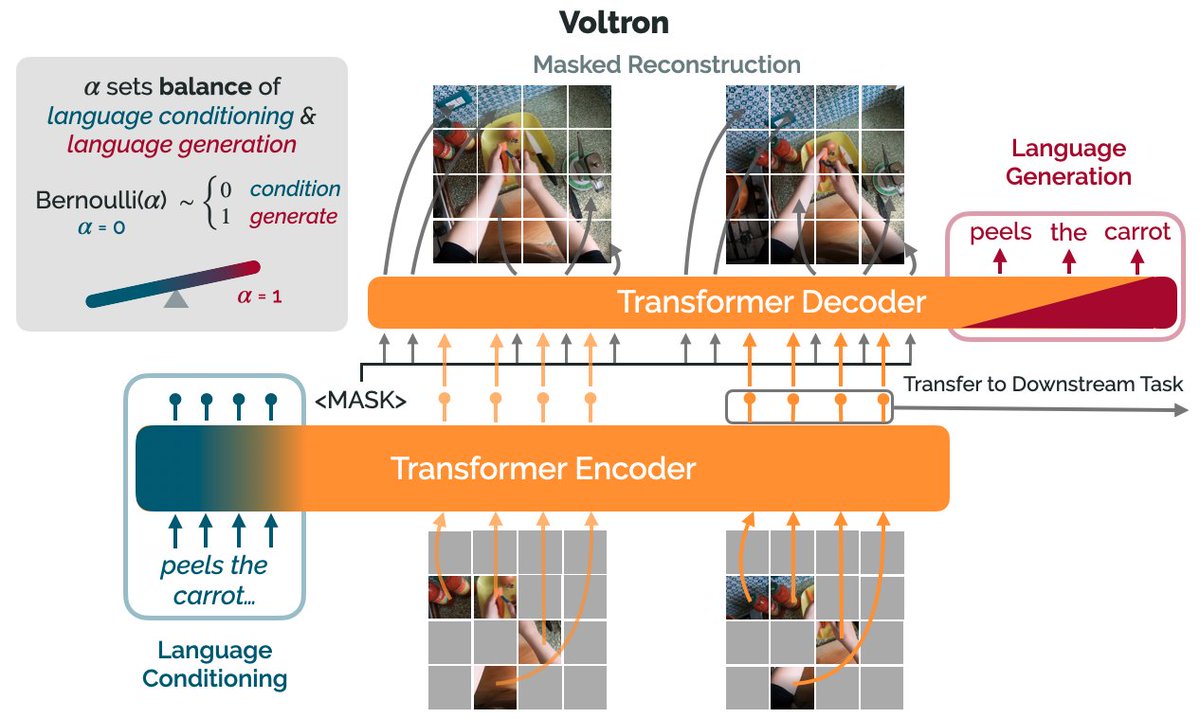
The Voltron framework offers a simple way to use language supervision to shape representation learning, building off of prior work in representations for robotics like MVP (https://t.co/Pb0mk9hb4i) and R3M (https://t.co/o2Fkc3fP0e).
The secret is *balance* (3/12)
Starting with a masked autoencoder over frames from these video clips, make a choice:
1) Condition on language and improve our ability to reconstruct the scene.
2) Generate language given the visual representation and improve our ability to describe what's happening. (4/12)
By trading off *conditioning* and *generation* we show that we can learn 1) better representations than prior methods, and 2) explicitly shape the balance of low and high-level features captured.
Why is the ability to shape this balance important? (5/12)
Introducing Voltron: Language-Driven Representation Learning for Robotics!
Paper: https://t.co/gIsRPtSjKz
Models: https://t.co/NOB3cpATYG
Evaluation: https://t.co/aOzQu95J8z
🧵👇(1 / 12)
Videos of humans performing everyday tasks (Something-Something-v2, Ego4D) offer a rich and diverse resource for learning representations for robotic manipulation.
Yet, an underused part of these datasets are the rich, natural language annotations accompanying each video. (2/12)
The Voltron framework offers a simple way to use language supervision to shape representation learning, building off of prior work in representations for robotics like MVP (https://t.co/Pb0mk9hb4i) and R3M (https://t.co/o2Fkc3fP0e).
The secret is *balance* (3/12)
Starting with a masked autoencoder over frames from these video clips, make a choice:
1) Condition on language and improve our ability to reconstruct the scene.
2) Generate language given the visual representation and improve our ability to describe what's happening. (4/12)
By trading off *conditioning* and *generation* we show that we can learn 1) better representations than prior methods, and 2) explicitly shape the balance of low and high-level features captured.
Why is the ability to shape this balance important? (5/12)
You May Also Like




This is NONSENSE. The people who take photos with their books on instagram are known to be voracious readers who graciously take time to review books and recommend them to their followers. Part of their medium is to take elaborate, beautiful photos of books. Die mad, Guardian.
THEY DO READ THEM, YOU JUDGY, RACOON-PICKED TRASH BIN

If you come for Bookstagram, i will fight you.
In appreciation, here are some of my favourite bookstagrams of my books: (photos by lit_nerd37, mybookacademy, bookswrotemystory, and scorpio_books)

Beautifully read: why bookselfies are all over Instagram https://t.co/pBQA3JY0xm
— Guardian Books (@GuardianBooks) October 30, 2018
THEY DO READ THEM, YOU JUDGY, RACOON-PICKED TRASH BIN
If you come for Bookstagram, i will fight you.
In appreciation, here are some of my favourite bookstagrams of my books: (photos by lit_nerd37, mybookacademy, bookswrotemystory, and scorpio_books)