More from All



Margatha Natarajar murthi - Uthirakosamangai temple near Ramanathapuram,TN
#ArudraDarisanam
Unique Natarajar made of emerlad is abt 6 feet tall.
It is always covered with sandal paste.Only on Thriuvadhirai Star in month Margazhi-Nataraja can be worshipped without sandal paste.
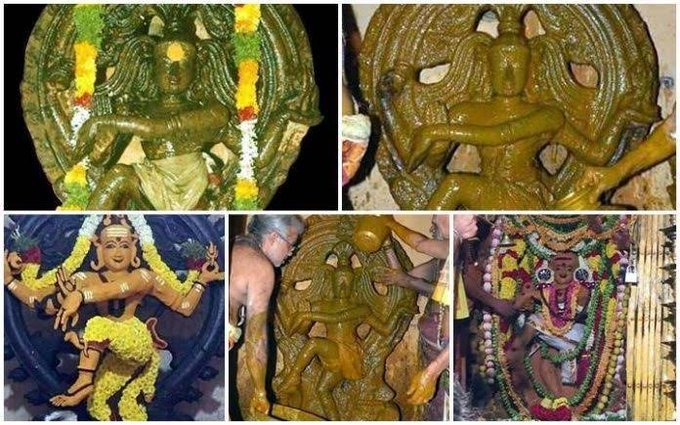
After removing the sandal paste,day long rituals & various abhishekam will be https://t.co/e1Ye8DrNWb day Maragatha Nataraja sannandhi will be closed after anointing the murthi with fresh sandal paste.Maragatha Natarajar is covered with sandal paste throughout the year
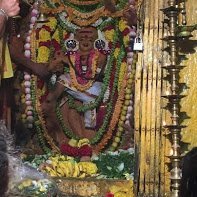
as Emerald has scientific property of its molecules getting disturbed when exposed to light/water/sound.This is an ancient Shiva temple considered to be 3000 years old -believed to be where Bhagwan Shiva gave Veda gyaana to Parvati Devi.This temple has some stunning sculptures.
#ArudraDarisanam
Unique Natarajar made of emerlad is abt 6 feet tall.
It is always covered with sandal paste.Only on Thriuvadhirai Star in month Margazhi-Nataraja can be worshipped without sandal paste.
After removing the sandal paste,day long rituals & various abhishekam will be https://t.co/e1Ye8DrNWb day Maragatha Nataraja sannandhi will be closed after anointing the murthi with fresh sandal paste.Maragatha Natarajar is covered with sandal paste throughout the year
as Emerald has scientific property of its molecules getting disturbed when exposed to light/water/sound.This is an ancient Shiva temple considered to be 3000 years old -believed to be where Bhagwan Shiva gave Veda gyaana to Parvati Devi.This temple has some stunning sculptures.


How can we use language supervision to learn better visual representations for robotics?
Introducing Voltron: Language-Driven Representation Learning for Robotics!
Paper: https://t.co/gIsRPtSjKz
Models: https://t.co/NOB3cpATYG
Evaluation: https://t.co/aOzQu95J8z
🧵👇(1 / 12)
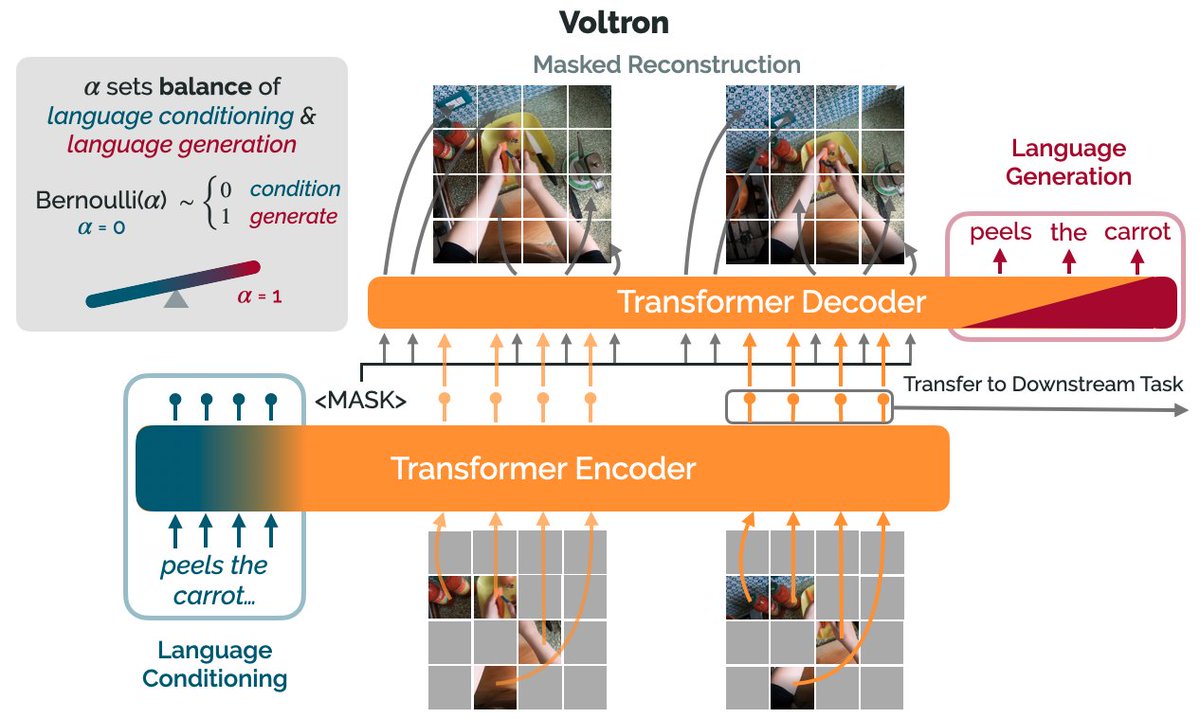
Videos of humans performing everyday tasks (Something-Something-v2, Ego4D) offer a rich and diverse resource for learning representations for robotic manipulation.
Yet, an underused part of these datasets are the rich, natural language annotations accompanying each video. (2/12)
The Voltron framework offers a simple way to use language supervision to shape representation learning, building off of prior work in representations for robotics like MVP (https://t.co/Pb0mk9hb4i) and R3M (https://t.co/o2Fkc3fP0e).
The secret is *balance* (3/12)
Starting with a masked autoencoder over frames from these video clips, make a choice:
1) Condition on language and improve our ability to reconstruct the scene.
2) Generate language given the visual representation and improve our ability to describe what's happening. (4/12)
By trading off *conditioning* and *generation* we show that we can learn 1) better representations than prior methods, and 2) explicitly shape the balance of low and high-level features captured.
Why is the ability to shape this balance important? (5/12)
Introducing Voltron: Language-Driven Representation Learning for Robotics!
Paper: https://t.co/gIsRPtSjKz
Models: https://t.co/NOB3cpATYG
Evaluation: https://t.co/aOzQu95J8z
🧵👇(1 / 12)
Videos of humans performing everyday tasks (Something-Something-v2, Ego4D) offer a rich and diverse resource for learning representations for robotic manipulation.
Yet, an underused part of these datasets are the rich, natural language annotations accompanying each video. (2/12)
The Voltron framework offers a simple way to use language supervision to shape representation learning, building off of prior work in representations for robotics like MVP (https://t.co/Pb0mk9hb4i) and R3M (https://t.co/o2Fkc3fP0e).
The secret is *balance* (3/12)
Starting with a masked autoencoder over frames from these video clips, make a choice:
1) Condition on language and improve our ability to reconstruct the scene.
2) Generate language given the visual representation and improve our ability to describe what's happening. (4/12)
By trading off *conditioning* and *generation* we show that we can learn 1) better representations than prior methods, and 2) explicitly shape the balance of low and high-level features captured.
Why is the ability to shape this balance important? (5/12)
You May Also Like

My top 10 tweets of the year
A thread 👇
https://t.co/xj4js6shhy
https://t.co/b81zoW6u1d
https://t.co/1147it02zs
https://t.co/A7XCU5fC2m
A thread 👇
https://t.co/xj4js6shhy
Entrepreneur\u2019s mind.
— James Clear (@JamesClear) August 22, 2020
Athlete\u2019s body.
Artist\u2019s soul.
https://t.co/b81zoW6u1d
When you choose who to follow on Twitter, you are choosing your future thoughts.
— James Clear (@JamesClear) October 3, 2020
https://t.co/1147it02zs
Working on a problem reduces the fear of it.
— James Clear (@JamesClear) August 30, 2020
It\u2019s hard to fear a problem when you are making progress on it\u2014even if progress is imperfect and slow.
Action relieves anxiety.
https://t.co/A7XCU5fC2m
We often avoid taking action because we think "I need to learn more," but the best way to learn is often by taking action.
— James Clear (@JamesClear) September 23, 2020