Barlow Twins: a new super-simple self-supervised method to train joint-embedding architectures (aka Siamese nets) non

Basic idea: maximize the normalized correlation between a variable in the left branch and the same var in the right branch, while making the normalized cross-correlation between one var in the left branch and all other vars in the right branch as close to zero as possible.
2/N
In short: the loss tries to make the normalized cross-correlation between the embedding vectors coming out of the left branch and the right branch as close to the identity matrix as possible.
3/N
The 2 branches are always fed with differently-distorted version of the same image, and there is no need for dissimilar training pairs.

The objective makes the embedding vectors of the two branches as similar as possible, while maximizing their information content.
4/N
No contrastive samples, no huge batch size (optimal is 128), nor predictor, no moving-average weights, no vector quantization, nor cut gradients in one of the branches.
5/N
Competitive results on ImageNet with a linear classifier head.
Great results on semi-supervised ImageNet in the low labeled-data regime and on transfer tasks.
6/N
Results on ImageNet with linear classifier head
7/N
Results with 1% and 10% of ImagNet labeled images
8/N
Results on transfer tasks.
9/N
Arch is standard ResNet50 with 2048-D feature vec.
But contrary to others, the embedding size (projector output) is larger. The perf keeps going up as the embedding dim grows (we stopped at 16384).
Probably cause the feature vars are made independent, not just decorrelated.
10/N
Why Barlow? Horace Barlow was a pioneer of visual neuroscience who proposed the idea that the brain tries to minimize redundancy in representations.

By Jure Zbontar, Li Jing, Ishan Misra, yours truly, and Stéphane Deny.
All from FAIR.
To appear at ICML 2021
11/N
Don't you just hate slicing what would be a decent-size post into threaded thin tweets?
12/N
No, really. Don't you hate reading those long thread slices?
If you do, you could just read my Facebook post:
https://t.co/dQii7BEPQ5
13/N
N=13
Typo: optimal batch size is 1024, not 128.
14/13 (haha).

More from All

Master Thread of all my threads!

Hello!! 👋

• I have curated some of the best tweets from the best traders we know of.

• Making one master thread and will keep posting all my threads under this.

• Go through this for super learning/value totally free of cost! 😃

1. 7 FREE OPTION TRADING COURSES FOR


2. THE ABSOLUTE BEST 15 SCANNERS EXPERTS ARE USING

Got these scanners from the following accounts:

1. @Pathik_Trader
2. @sanjufunda
3. @sanstocktrader
4. @SouravSenguptaI
5. @Rishikesh_ADX


3. 12 TRADING SETUPS which experts are using.

These setups I found from the following 4 accounts:

1. @Pathik_Trader
2. @sourabhsiso19
3. @ITRADE191
4.


4. Curated tweets on HOW TO SELL STRADDLES.

Everything covered in this thread.
1. Management
2. How to initiate
3. When to exit straddles
4. Examples
5. Videos on

You May Also Like

@EricTopol @NBA @StephenKissler @yhgrad B.1.1.7 reveals clearly that SARS-CoV-2 is reverting to its original pre-outbreak condition, i.e. adapted to transgenic hACE2 mice (either Baric's BALB/c ones or others used at WIV labs during chimeric bat coronavirus experiments aimed at developing a pan betacoronavirus vaccine)

@NBA @StephenKissler @yhgrad 1. From Day 1, SARS-COV-2 was very well adapted to humans .....and transgenic hACE2 Mice


@NBA @StephenKissler @yhgrad 2. High Probability of serial passaging in Transgenic Mice expressing hACE2 in genesis of SARS-COV-2


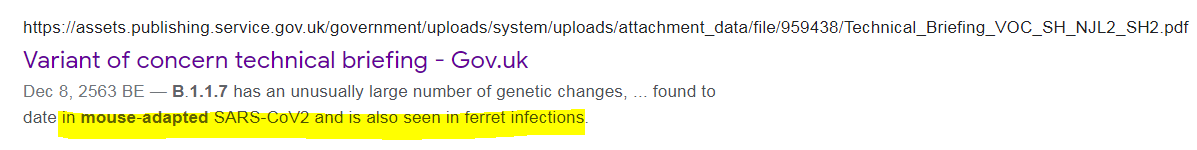
@NBA @StephenKissler @yhgrad B.1.1.7 has an unusually large number of genetic changes, ... found to date in mouse-adapted SARS-CoV2 and is also seen in ferret infections.
https://t.co/9Z4oJmkcKj


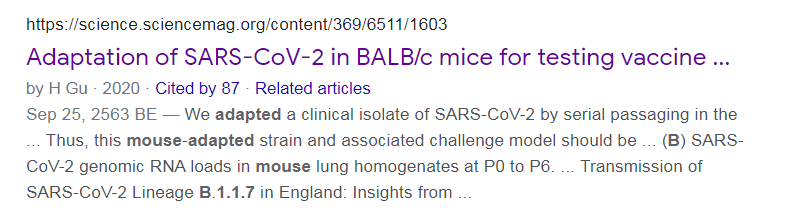
@NBA @StephenKissler @yhgrad We adapted a clinical isolate of SARS-CoV-2 by serial passaging in the ... Thus, this mouse-adapted strain and associated challenge model should be ... (B) SARS-CoV-2 genomic RNA loads in mouse lung homogenates at P0 to P6.
https://t.co/I90OOCJg7o
The first ever world map was sketched thousands of years ago by Indian saint
“Ramanujacharya” who simply translated the following verse from Mahabharat and gave the world its real face

In Mahabharat,it is described how 'Maharishi Ved Vyasa' gave away his divine vision to Sanjay


Dhritarashtra's charioteer so that he could describe him the events of the upcoming war.

But, even before questions of war could begin, Dhritarashtra asked him to describe how the world looks like from space.

This is how he described the face of the world:

सुदर्शनं प्रवक्ष्यामि द्वीपं तु कुरुनन्दन। परिमण्डलो महाराज द्वीपोऽसौ चक्रसंस्थितः॥
यथा हि पुरुषः पश्येदादर्शे मुखमात्मनः। एवं सुदर्शनद्वीपो दृश्यते चन्द्रमण्डले॥ द्विरंशे पिप्पलस्तत्र द्विरंशे च शशो महान्।

—वेद व्यास, भीष्म पर्व, महाभारत


Meaning:-

हे कुरुनन्दन ! सुदर्शन नामक यह द्वीप चक्र की भाँति गोलाकार स्थित है, जैसे पुरुष दर्पण में अपना मुख देखता है, उसी प्रकार यह द्वीप चन्द्रमण्डल में दिखायी देता है। इसके दो अंशो मे पीपल और दो अंशो मे विशाल शश (खरगोश) दिखायी देता है।


Meaning: "Just like a man sees his face in the mirror, so does the Earth appears in the Universe. In the first part you see leaves of the Peepal Tree, and in the next part you see a Rabbit."

Based on this shloka, Saint Ramanujacharya sketched out the map, but the world laughed