
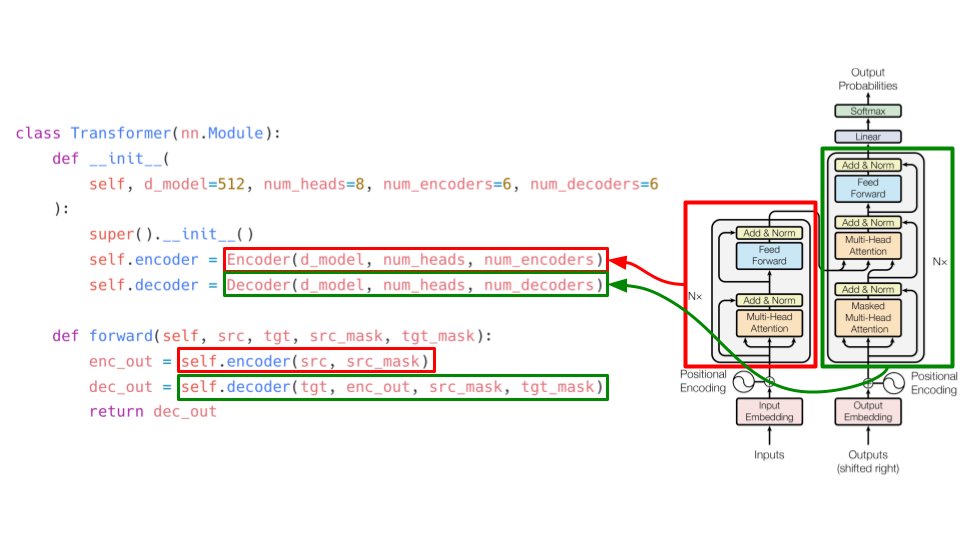
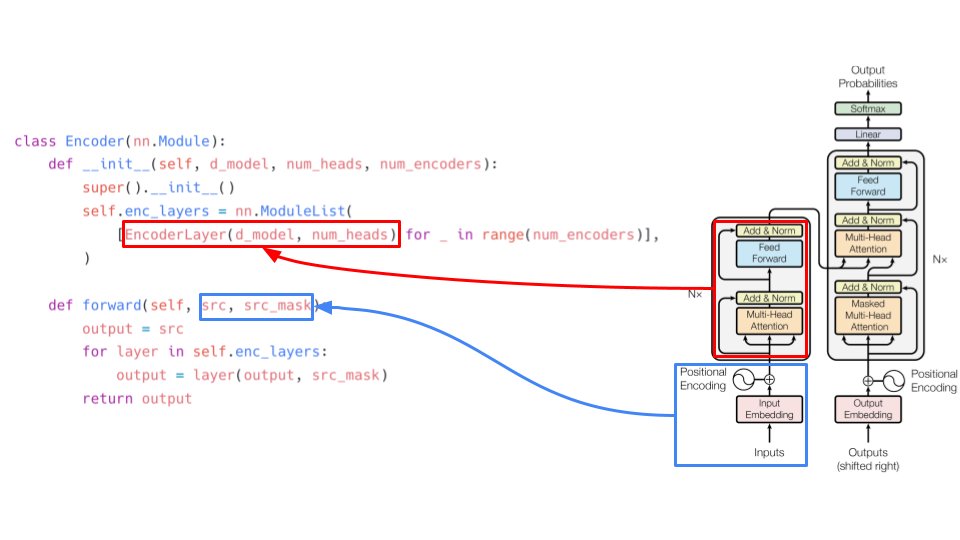
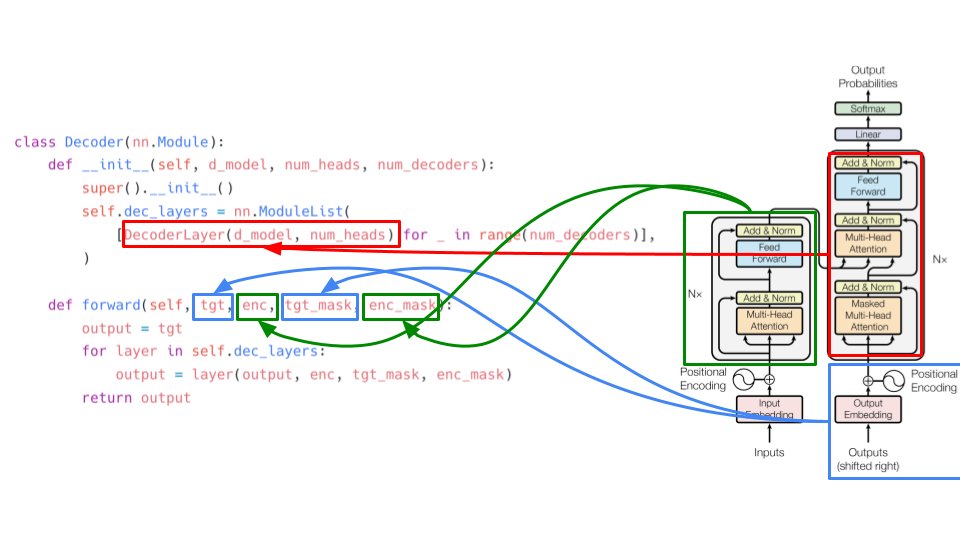
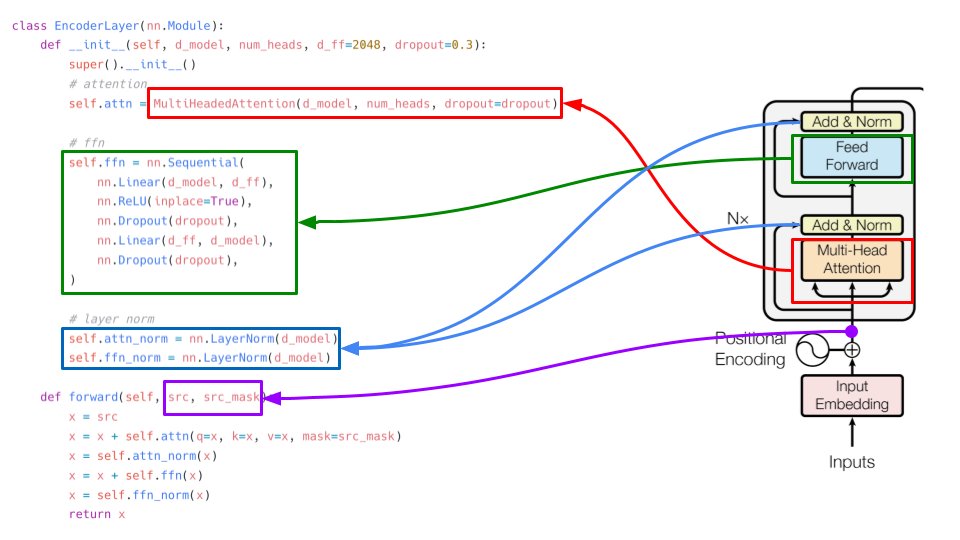
"Attention is all you need" implementation from scratch in PyTorch. A Twitter thread:
1/


More from All






You May Also Like

A THREAD ON @SarangSood
Decoded his way of analysis/logics for everyone to easily understand.
Have covered:
1. Analysis of volatility, how to foresee/signs.
2. Workbook
3. When to sell options
4. Diff category of days
5. How movement of option prices tell us what will happen
1. Keeps following volatility super closely.
Makes 7-8 different strategies to give him a sense of what's going on.
Whichever gives highest profit he trades in.
2. Theta falls when market moves.
Falls where market is headed towards not on our original position.
3. If you're an options seller then sell only when volatility is dropping, there is a high probability of you making the right trade and getting profit as a result
He believes in a market operator, if market mover sells volatility Sarang Sir joins him.
4. Theta decay vs Fall in vega
Sell when Vega is falling rather than for theta decay. You won't be trapped and higher probability of making profit.
Decoded his way of analysis/logics for everyone to easily understand.
Have covered:
1. Analysis of volatility, how to foresee/signs.
2. Workbook
3. When to sell options
4. Diff category of days
5. How movement of option prices tell us what will happen
1. Keeps following volatility super closely.
Makes 7-8 different strategies to give him a sense of what's going on.
Whichever gives highest profit he trades in.
I am quite different from your style. I follow the market's volatility very closely. I have mock positions in 7-8 different strategies which allows me to stay connected. Whichever gives best profit is usually the one i trade in.
— Sarang Sood (@SarangSood) August 13, 2019
2. Theta falls when market moves.
Falls where market is headed towards not on our original position.
Anilji most of the time these days Theta only falls when market moves. So the Theta actually falls where market has moved to, not where our position was in the first place. By shifting we can come close to capturing the Theta fall but not always.
— Sarang Sood (@SarangSood) June 24, 2019
3. If you're an options seller then sell only when volatility is dropping, there is a high probability of you making the right trade and getting profit as a result
He believes in a market operator, if market mover sells volatility Sarang Sir joins him.
This week has been great so far. The main aim is to be in the right side of the volatility, rest the market will reward.
— Sarang Sood (@SarangSood) July 3, 2019
4. Theta decay vs Fall in vega
Sell when Vega is falling rather than for theta decay. You won't be trapped and higher probability of making profit.
There is a difference between theta decay & fall in vega. Decay is certain but there is no guaranteed profit as delta moves can increase cost. Fall in vega on the other hand is backed by a powerful force that sells options and gives handsome returns. Our job is to identify them.
— Sarang Sood (@SarangSood) February 12, 2020

And here they are...
THE WINNERS OF THE 24 HOUR STARTUP CHALLENGE
Remember, this money is just fun. If you launched a product (or even attempted a launch) - you did something worth MUCH more than $1,000.
#24hrstartup
The winners 👇
#10
Lattes For Change - Skip a latte and save a life.
https://t.co/M75RAirZzs
@frantzfries built a platform where you can see how skipping your morning latte could do for the world.
A great product for a great cause.
Congrats Chris on winning $250!
#9
Instaland - Create amazing landing pages for your followers.
https://t.co/5KkveJTAsy
A team project! @bpmct and @BaileyPumfleet built a tool for social media influencers to create simple "swipe up" landing pages for followers.
Really impressive for 24 hours. Congrats!
#8
SayHenlo - Chat without distractions
https://t.co/og0B7gmkW6
Built by @DaltonEdwards, it's a platform for combatting conversation overload. This product was also coded exclusively from an iPad 😲
Dalton is a beast. I'm so excited he placed in the top 10.
#7
CoderStory - Learn to code from developers across the globe!
https://t.co/86Ay6nF4AY
Built by @jesswallaceuk, the project is focused on highlighting the experience of developers and people learning to code.
I wish this existed when I learned to code! Congrats on $250!!
THE WINNERS OF THE 24 HOUR STARTUP CHALLENGE
Remember, this money is just fun. If you launched a product (or even attempted a launch) - you did something worth MUCH more than $1,000.
#24hrstartup
The winners 👇
#10
Lattes For Change - Skip a latte and save a life.
https://t.co/M75RAirZzs
@frantzfries built a platform where you can see how skipping your morning latte could do for the world.
A great product for a great cause.
Congrats Chris on winning $250!
#9
Instaland - Create amazing landing pages for your followers.
https://t.co/5KkveJTAsy
A team project! @bpmct and @BaileyPumfleet built a tool for social media influencers to create simple "swipe up" landing pages for followers.
Really impressive for 24 hours. Congrats!
#8
SayHenlo - Chat without distractions
https://t.co/og0B7gmkW6
Built by @DaltonEdwards, it's a platform for combatting conversation overload. This product was also coded exclusively from an iPad 😲
Dalton is a beast. I'm so excited he placed in the top 10.
#7
CoderStory - Learn to code from developers across the globe!
https://t.co/86Ay6nF4AY
Built by @jesswallaceuk, the project is focused on highlighting the experience of developers and people learning to code.
I wish this existed when I learned to code! Congrats on $250!!



1/x Fort Detrick History
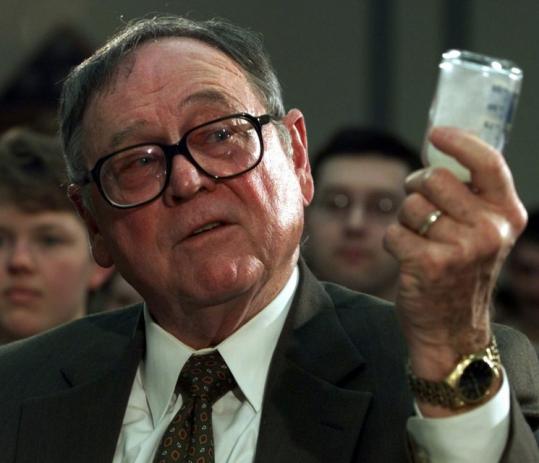
Mr. Patrick, one of the chief scientists at the Army Biological Warfare Laboratories at Fort Detrick in Frederick, Md., held five classified US patents for the process of weaponizing anthrax.
2/x
Under Mr. Patrick’s direction, scientists at Fort Detrick developed a tularemia agent that, if disseminated by airplane, could cause casualties & sickness over 1000s mi². In a 10,000 mi² range, it had 90% casualty rate & 50% fatality rate
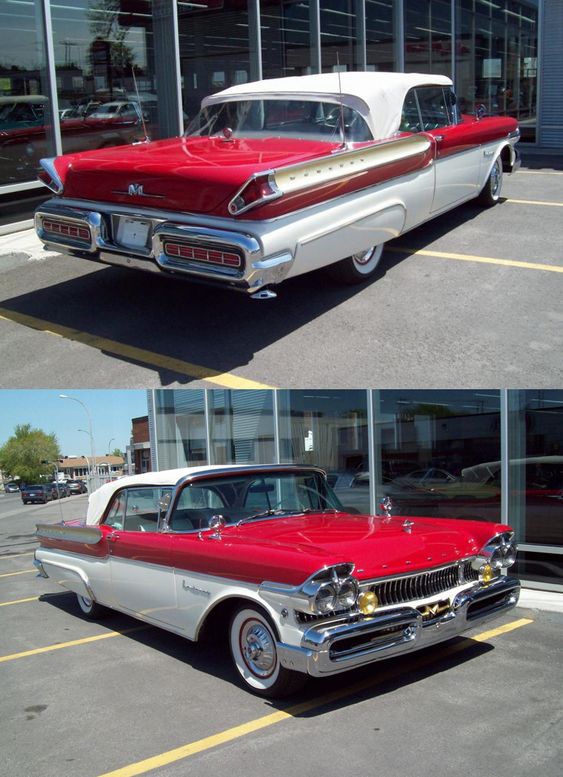
3/x His team explored Q fever, plague, & Venezuelan equine encephalitis, testing more than 20 anthrax strains to discern most lethal variety. Fort Detrick scientists used aerosol spray systems inside fountain pens, walking sticks, light bulbs, & even in 1953 Mercury exhaust pipes
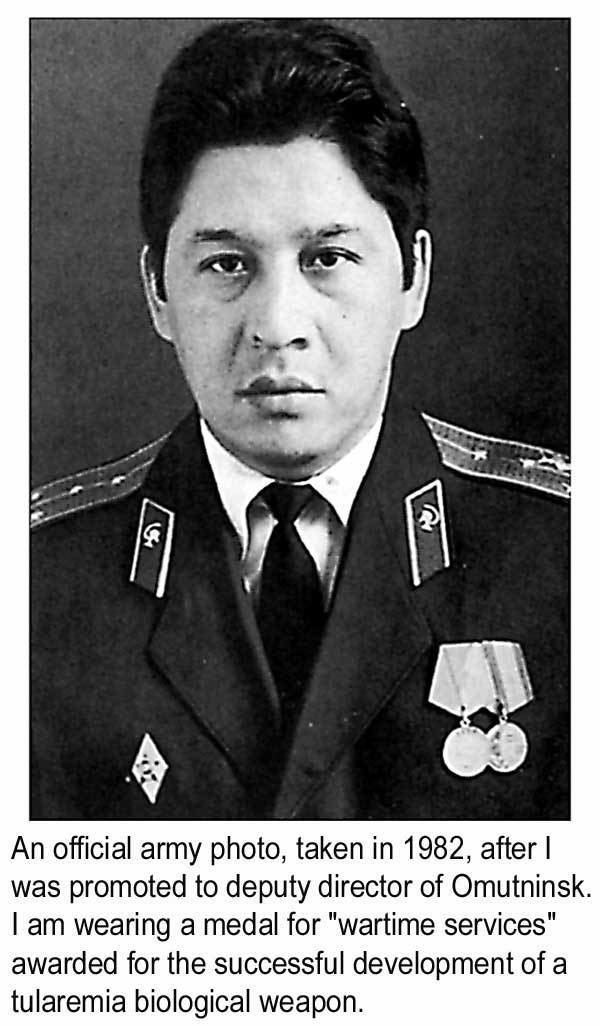
4/x After retiring in 1986, Mr. Patrick remained one of the world’s foremost specialists on biological warfare & was a consultant to the CIA, FBI, & US military. He debriefed Soviet defector Ken Alibek, the deputy chief of the Soviet biowarfare program
https://t.co/sHqSaTSqtB
5/x Back in Time
In 1949 the Army created a small team of chemists at "Camp Detrick" called Special Operations Division. Its assignment was to find military uses for toxic bacteria. The coercive use of toxins was a new field, which fascinated Allen Dulles, later head of the CIA
Mr. Patrick, one of the chief scientists at the Army Biological Warfare Laboratories at Fort Detrick in Frederick, Md., held five classified US patents for the process of weaponizing anthrax.
2/x
Under Mr. Patrick’s direction, scientists at Fort Detrick developed a tularemia agent that, if disseminated by airplane, could cause casualties & sickness over 1000s mi². In a 10,000 mi² range, it had 90% casualty rate & 50% fatality rate
3/x His team explored Q fever, plague, & Venezuelan equine encephalitis, testing more than 20 anthrax strains to discern most lethal variety. Fort Detrick scientists used aerosol spray systems inside fountain pens, walking sticks, light bulbs, & even in 1953 Mercury exhaust pipes
4/x After retiring in 1986, Mr. Patrick remained one of the world’s foremost specialists on biological warfare & was a consultant to the CIA, FBI, & US military. He debriefed Soviet defector Ken Alibek, the deputy chief of the Soviet biowarfare program
https://t.co/sHqSaTSqtB
5/x Back in Time
In 1949 the Army created a small team of chemists at "Camp Detrick" called Special Operations Division. Its assignment was to find military uses for toxic bacteria. The coercive use of toxins was a new field, which fascinated Allen Dulles, later head of the CIA