I have distracted myself this week with the extraordinarily mundane task of designing a sample identifier scheme. I want to share some decisions I made in the hope that it saves somebody else some time.
https://t.co/DAms8Jj6A7
https://t.co/T2hKbvpCPy

https://t.co/8vng8TW3Hf
this would never have happened with our diceware labels pic.twitter.com/6JYbVk70LR
— Sam Nicholls (@samstudio8) February 12, 2020
More from Society


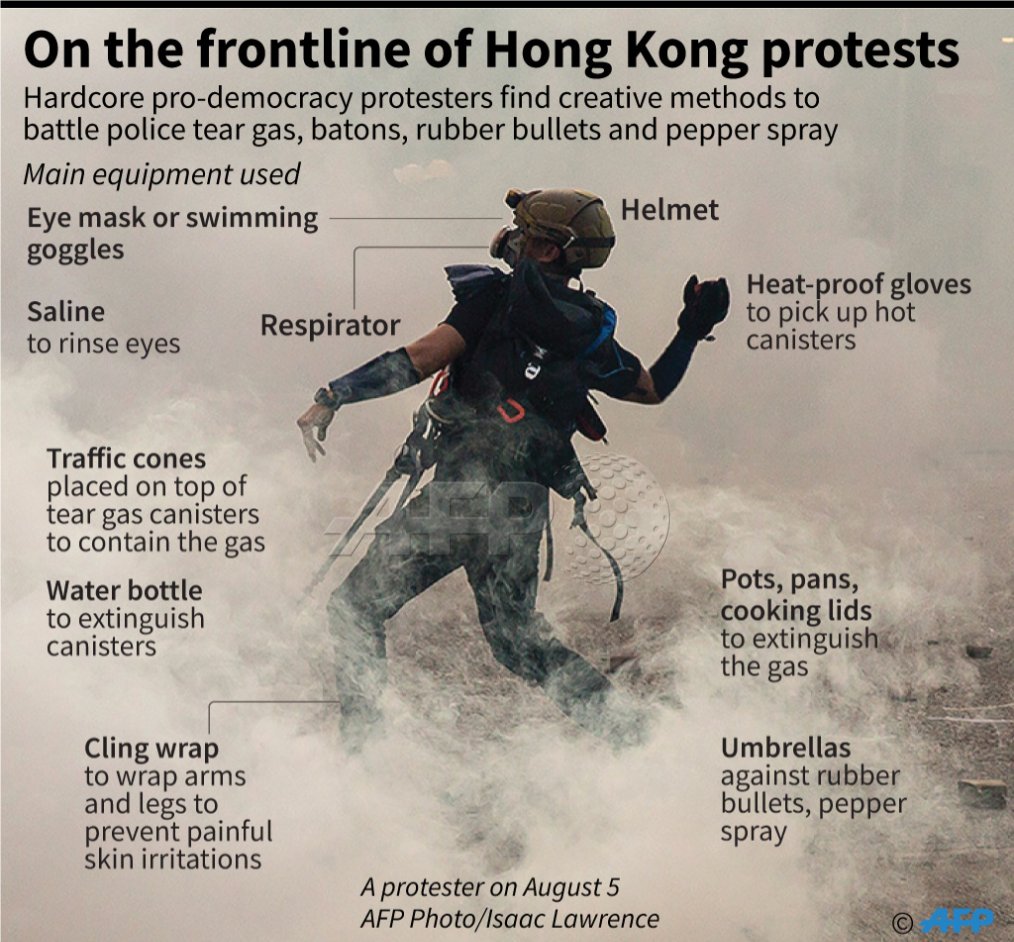
Hong Kong protester equipment list:
- respirator (dubbed "pig snouts" in Cantonese)
- helmet
- eye mask
- heat-proof gloves
- water bottle
- cling wrap
- saline
- traffic cones
- pots and pans
Demonstrators find creative methods to battle police tear gas
https://t.co/kPeUTu9iFh
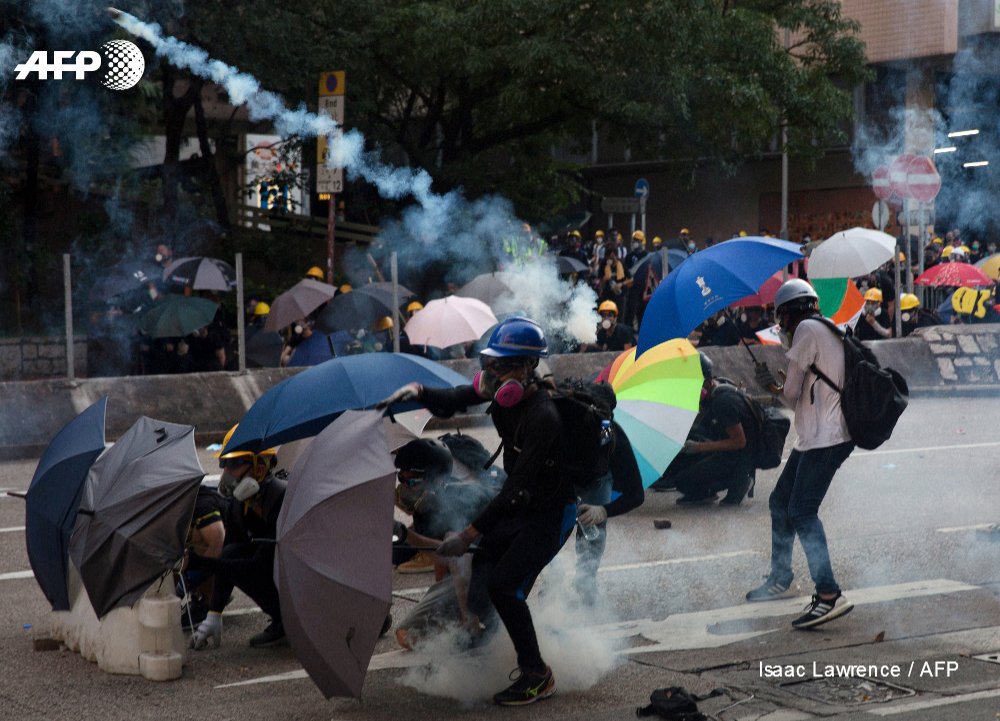
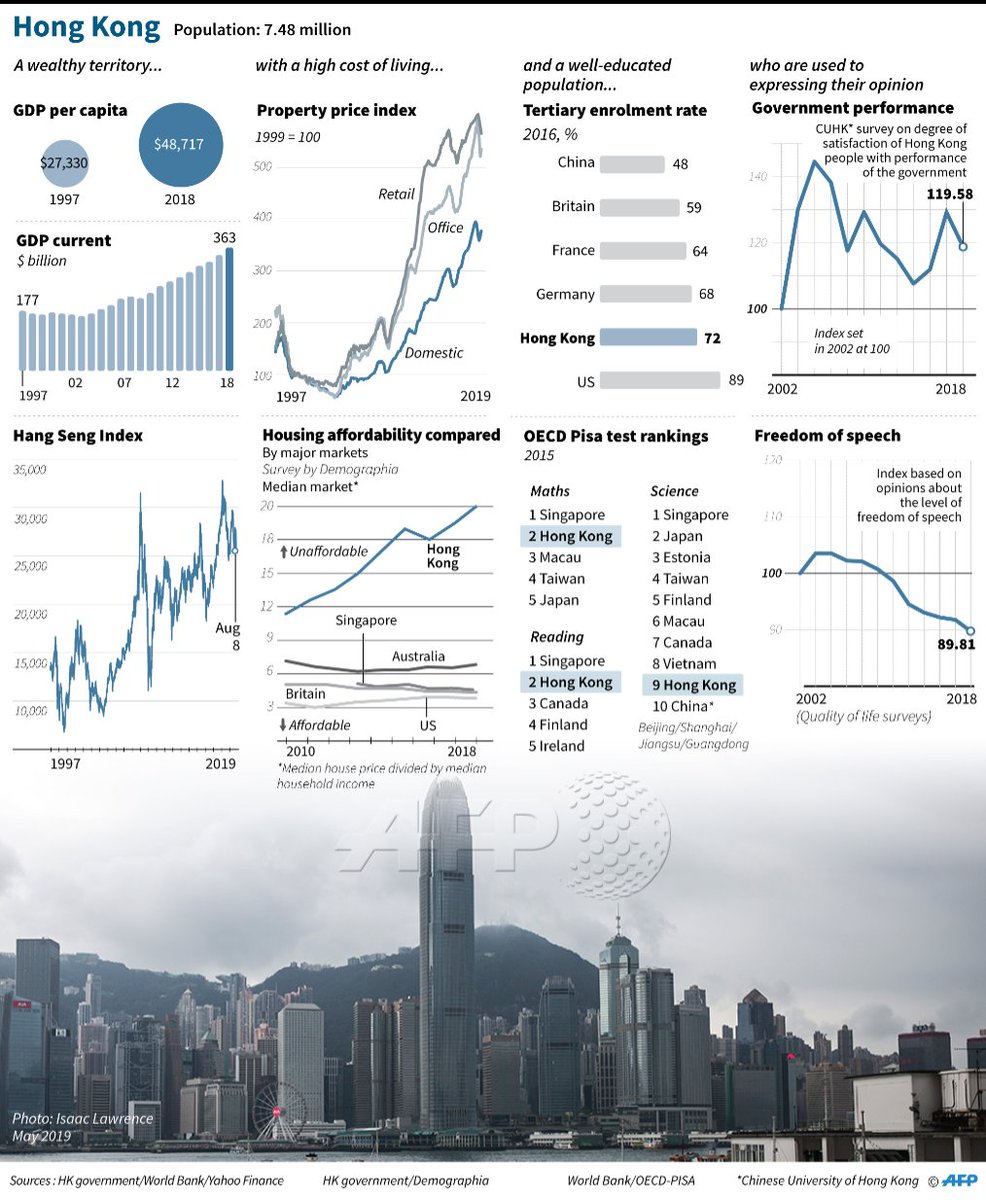
AFP graphic charting Hong Kong's main socio-economic indicators and opinion polls on press freedom and government performance
@AFPgraphics
AFP graphic showing the main equipment used by hardcore pro-democracy protesters in Hong Kong to battle police tear gas, pepper spray and rubber bullets
@AFPgraphics
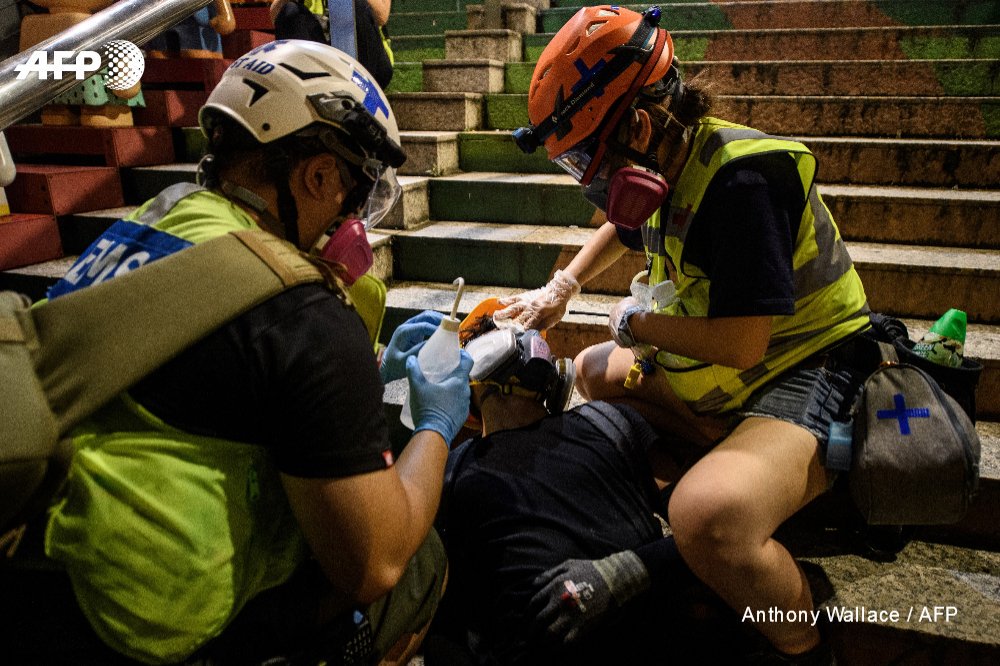
Frontline first aid.
Nurses, doctors, medical students and ordinary citizens with first aid training have clamoured to join a small volunteer corps helping treat people involved in the Hong Kong protests
@AFP's Yan Zhao reports: https://t.co/uDfYkMeZJf
📸 Anthony Wallace
Pro-democracy activists kick off three days of rallies at Hong Kong airport.
Protesters hope to win international support from arriving passengers. The last demonstration at the airport on July 26 passed off peacefully without causing flight disruptions
https://t.co/jmVqtEd4M2
- respirator (dubbed "pig snouts" in Cantonese)
- helmet
- eye mask
- heat-proof gloves
- water bottle
- cling wrap
- saline
- traffic cones
- pots and pans
Demonstrators find creative methods to battle police tear gas
https://t.co/kPeUTu9iFh
AFP graphic charting Hong Kong's main socio-economic indicators and opinion polls on press freedom and government performance
@AFPgraphics
AFP graphic showing the main equipment used by hardcore pro-democracy protesters in Hong Kong to battle police tear gas, pepper spray and rubber bullets
@AFPgraphics
Frontline first aid.
Nurses, doctors, medical students and ordinary citizens with first aid training have clamoured to join a small volunteer corps helping treat people involved in the Hong Kong protests
@AFP's Yan Zhao reports: https://t.co/uDfYkMeZJf
📸 Anthony Wallace
Pro-democracy activists kick off three days of rallies at Hong Kong airport.
Protesters hope to win international support from arriving passengers. The last demonstration at the airport on July 26 passed off peacefully without causing flight disruptions
https://t.co/jmVqtEd4M2


You May Also Like

Following @BAUDEGS I have experienced hateful and propagandist tweets time after time. I have been shocked that an academic community would be so reckless with their publications. So I did some research.
The question is:
Is this an official account for Bahcesehir Uni (Bau)?

Bahcesehir Uni, BAU has an official website https://t.co/ztzX6uj34V which links to their social media, leading to their Twitter account @Bahcesehir
BAU’s official Twitter account

BAU has many departments, which all have separate accounts. Nowhere among them did I find @BAUDEGS
@BAUOrganization @ApplyBAU @adayBAU @BAUAlumniCenter @bahcesehirfbe @baufens @CyprusBau @bauiisbf @bauglobal @bahcesehirebe @BAUintBatumi @BAUiletisim @BAUSaglik @bauebf @TIPBAU
Nowhere among them was @BAUDEGS to find

The question is:
Is this an official account for Bahcesehir Uni (Bau)?
Bahcesehir Uni, BAU has an official website https://t.co/ztzX6uj34V which links to their social media, leading to their Twitter account @Bahcesehir
BAU’s official Twitter account
BAU has many departments, which all have separate accounts. Nowhere among them did I find @BAUDEGS
@BAUOrganization @ApplyBAU @adayBAU @BAUAlumniCenter @bahcesehirfbe @baufens @CyprusBau @bauiisbf @bauglobal @bahcesehirebe @BAUintBatumi @BAUiletisim @BAUSaglik @bauebf @TIPBAU
Nowhere among them was @BAUDEGS to find

Fake chats claiming to be from the Irish African community are being disseminated by the far right in order to suggest that violence is imminent from #BLM supporters. This is straight out of the QAnon and Proud Boys playbook. Spread the word. Protest safely. #georgenkencho

There is co-ordination across the far right in Ireland now to stir both left and right in the hopes of creating a race war. Think critically! Fascists see the tragic killing of #georgenkencho, the grief of his community and pending investigation as a flashpoint for action.
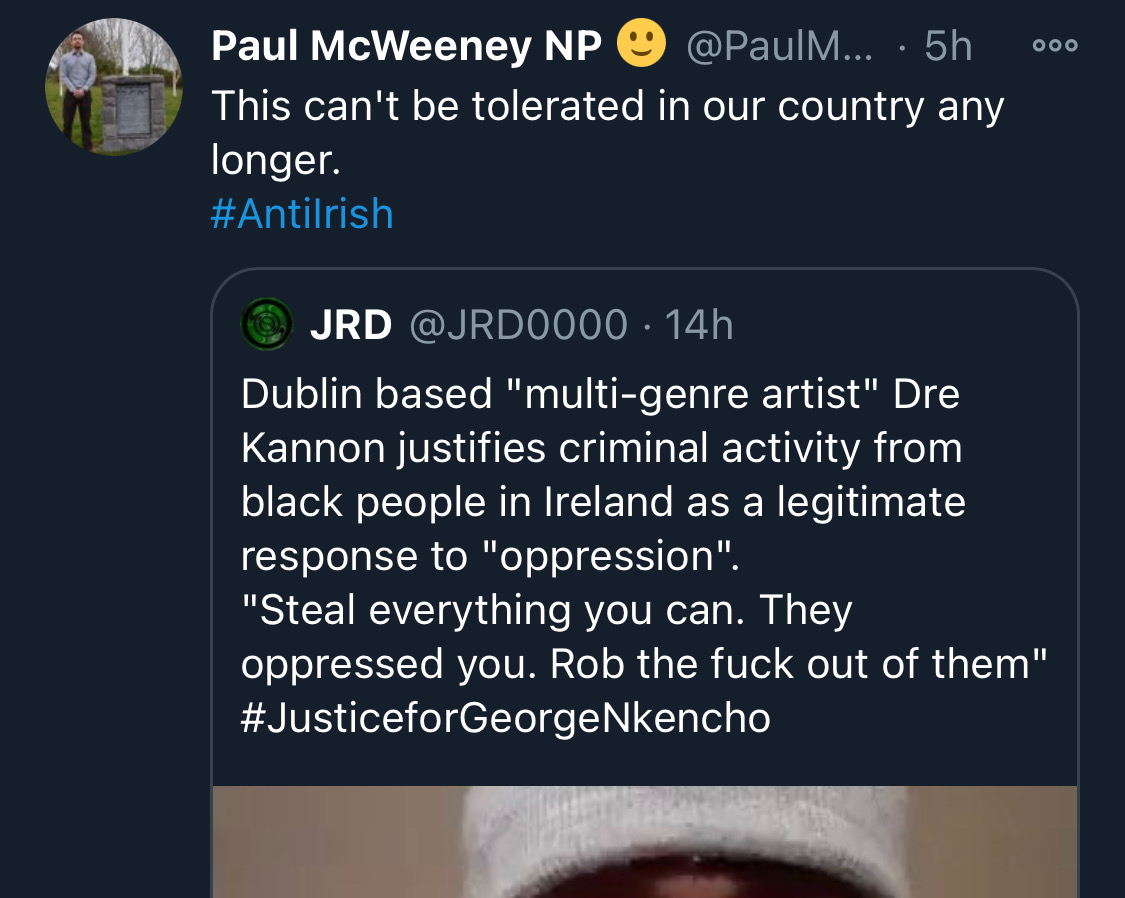
Across Telegram, Twitter and Facebook disinformation is being peddled on the back of these tragic events. From false photographs to the tactics ofwhite supremacy, the far right is clumsily trying to drive hate against minority groups and figureheads.
Declan Ganley’s Burkean group and the incel wing of National Party (Gearóid Murphy, Mick O’Keeffe & Co.) as well as all the usuals are concerted in their efforts to demonstrate their white supremacist cred. The quiet parts are today being said out loud.
The best thing you can do is challenge disinformation and report posts where engagement isn’t appropriate. Many of these are blatantly racist posts designed to drive recruitment to NP and other Nationalist groups. By all means protest but stay safe.
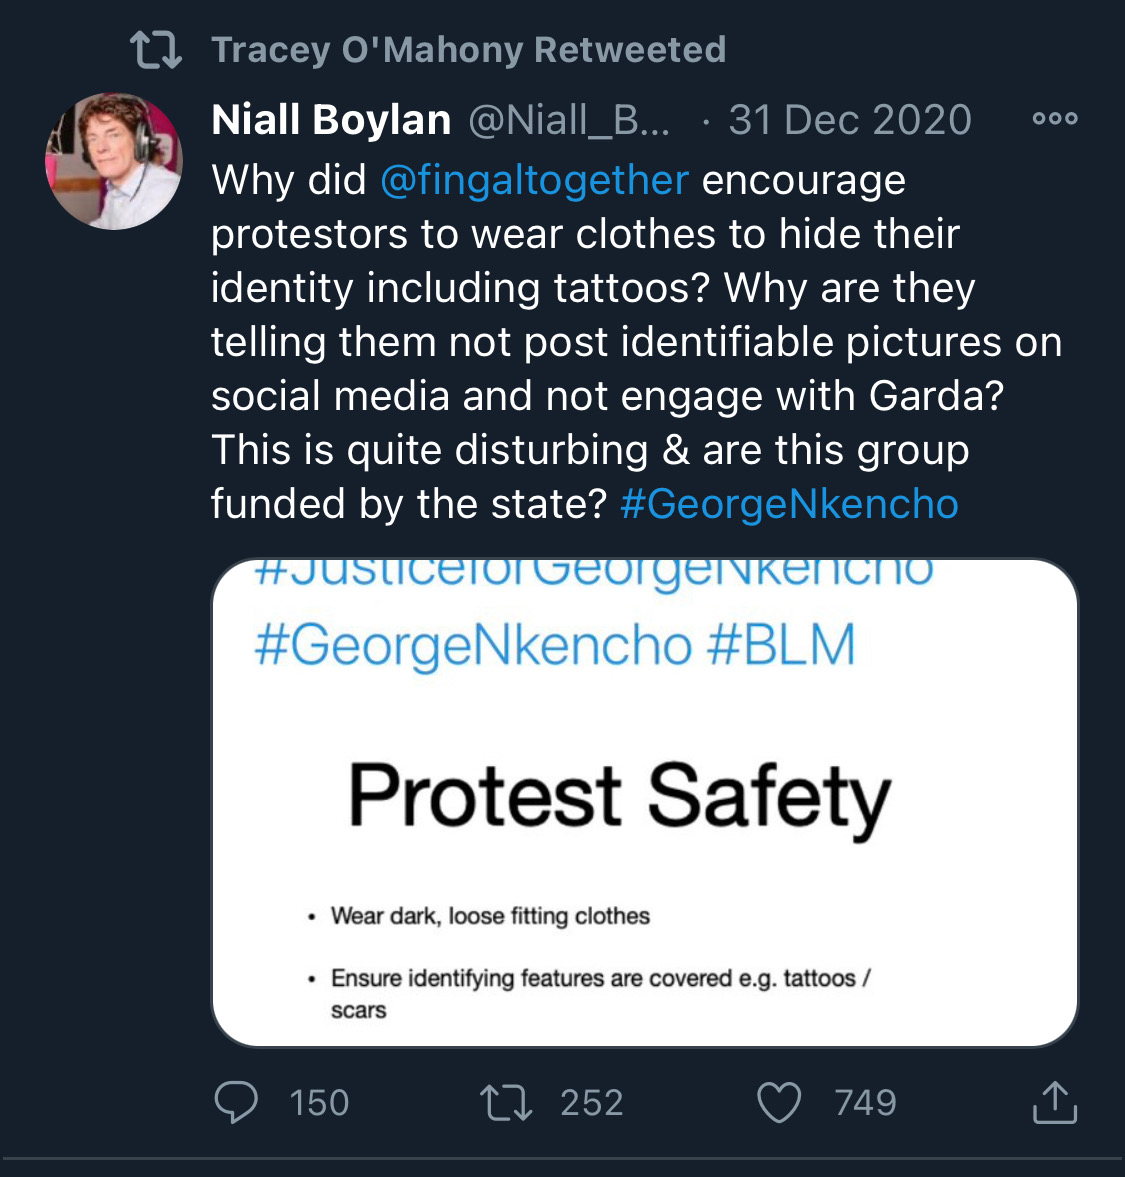
There is co-ordination across the far right in Ireland now to stir both left and right in the hopes of creating a race war. Think critically! Fascists see the tragic killing of #georgenkencho, the grief of his community and pending investigation as a flashpoint for action.
Across Telegram, Twitter and Facebook disinformation is being peddled on the back of these tragic events. From false photographs to the tactics ofwhite supremacy, the far right is clumsily trying to drive hate against minority groups and figureheads.
Be aware, the images the #farright are sharing in the hopes of starting a race war, are not of the SPAR employee that was punched. They\u2019re older photos of a Everton fan. Be aware of the information you\u2019re sharing and that it may be false. Always #factcheck #GeorgeNkencho pic.twitter.com/4c9w4CMk5h
— antifa.drone (@antifa_drone) December 31, 2020
Declan Ganley’s Burkean group and the incel wing of National Party (Gearóid Murphy, Mick O’Keeffe & Co.) as well as all the usuals are concerted in their efforts to demonstrate their white supremacist cred. The quiet parts are today being said out loud.
There is a concerted effort in far-right Telegram groups to try and incite violence on street by targetting people for racist online abuse following the killing of George Nkencho
— Mark Malone (@soundmigration) January 1, 2021
This follows on and is part of a misinformation campaign to polarise communities at this time.
The best thing you can do is challenge disinformation and report posts where engagement isn’t appropriate. Many of these are blatantly racist posts designed to drive recruitment to NP and other Nationalist groups. By all means protest but stay safe.